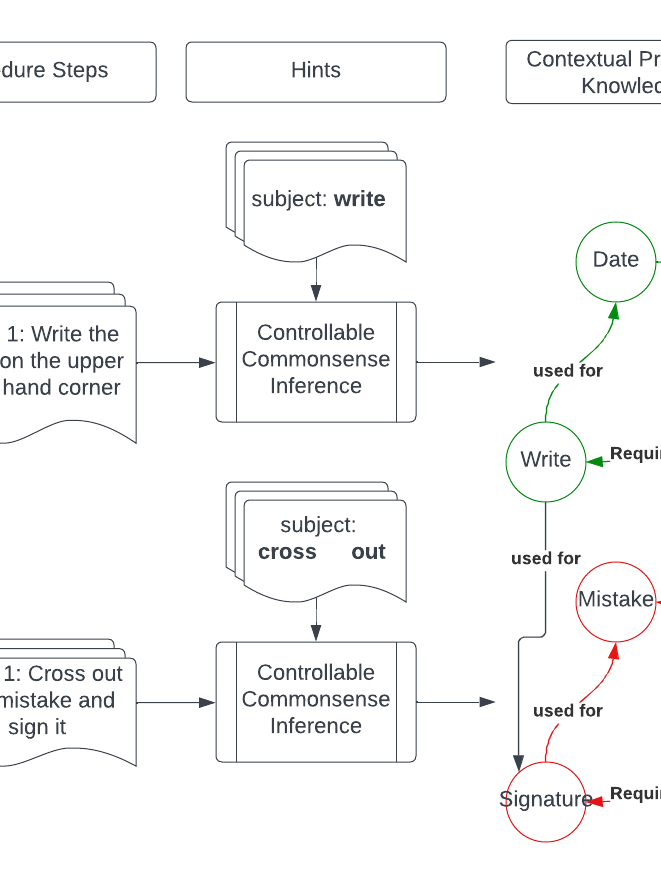
Continuing a thread from my Ph.D., I've been exploring whether structured commonsense knowledge can still help modern language models. On my fork of OpenMythos, an open-source recurrent-depth transformer, I added an optional channel that feeds ConceptNet embeddings into the model as concepts appear in the text. A second step walks one hop along ConceptNet to bring in related concepts the text doesn't mention.
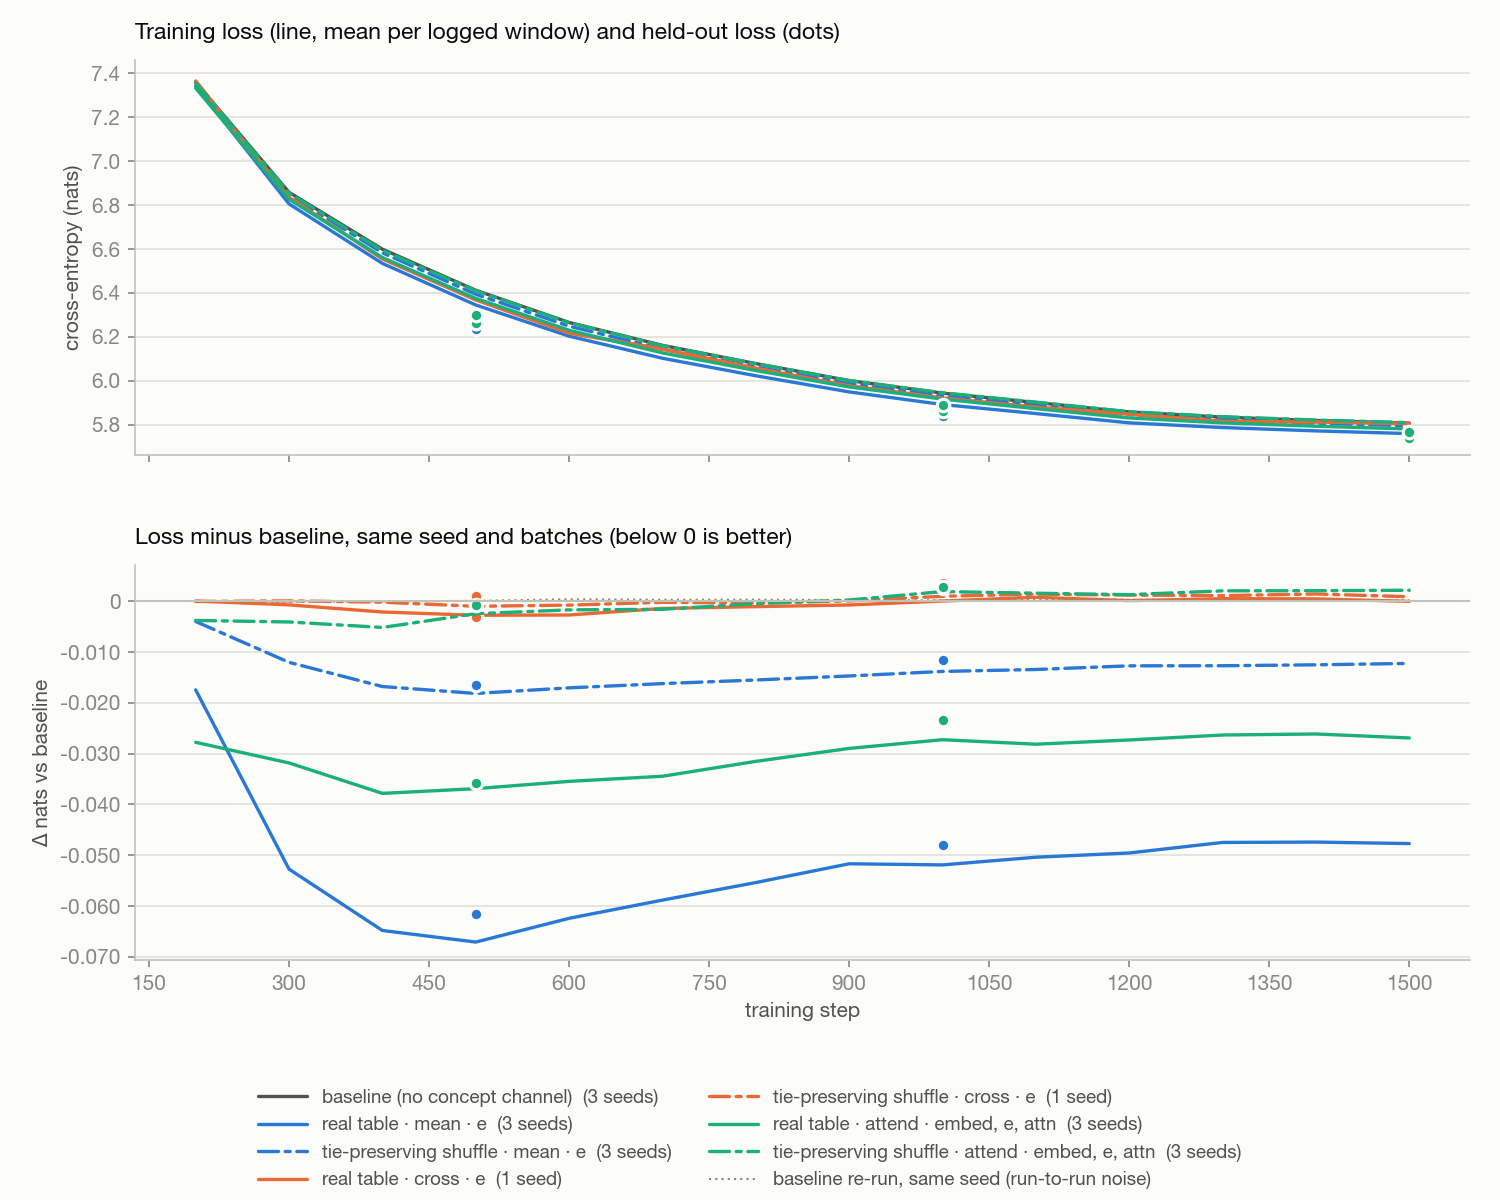
In small training runs, the real ConceptNet vectors lowered the loss compared to the same model without them. A shuffled version of the vectors helped much less, which suggests the gain comes from the knowledge itself rather than just the extra parameters.